A website backup is useful only if you can turn it into a working website when something goes wrong. A hosting dashboard may report that backups ran successfully, yet the archive could be missing the database, uploaded media, configuration, or credentials needed to recover. A safe restore test answers a different question: can your team actually bring the site back without damaging the live business? This guide explains how small-business owners can check recovery readiness, what to ask a developer or host, and how to record a repeatable test. It applies to content-managed sites, online stores, and custom websites, although the exact tools vary.
Why a successful backup is not proof of recovery
A green “backup complete” message normally confirms that a backup job finished according to its own rules. It does not necessarily confirm that every required component was captured or that the data can be restored into a usable application. A typical website may depend on files, a database, media storage, domain and DNS settings, secrets, server configuration, third-party integrations, and background jobs. Recovering only one part may produce a page that loads but cannot accept orders or enquiries. AWS guidance on testing data recovery emphasizes testing the actual ability to locate recovery points and restore them, rather than relying on backup creation alone.
1. Decide what a successful recovery must accomplish
Write down the functions your business cannot operate without. For a brochure website, this may include the homepage, contact form, email notifications, and key landing pages. For an online store, include product pages, checkout, order records, inventory updates, and customer communications. Set a realistic recovery time objective (RTO): how long the business can tolerate the service being unavailable. Also set a recovery point objective (RPO): how much recent data you can afford to lose. These are planning targets, not promises that your host can automatically meet. A site that receives frequent orders may need more frequent database backups than a rarely updated portfolio.
2. Inventory everything the backup must include
Ask whoever maintains the website to list its recoverable components: application code or CMS files, database, uploaded images and documents, themes and plugins, configuration files, server or container settings, and any scheduled jobs. Document what is not backed up, such as third-party email inboxes or external payment records. Keep a separate, securely managed record of which integrations must be reconnected after restoration. If the website has a custom application or multiple environments, confirm that the backup includes the correct production data source rather than an old staging database. This inventory prevents a false sense of security created by a large archive that omits critical dependencies.
3. Verify backup frequency, retention, and location
Confirm when the latest successful backup was created, how often new backups run, and how long older copies remain available. Ask whether files and database snapshots are taken at compatible times; restoring mismatched versions can produce missing references or unexpected application errors. Keep at least one protected copy outside the production server or account where feasible, so a server failure or compromised administrator account does not destroy every recovery option. Protect stored backups with encryption and limited access. A separate copy is not automatically an independent recovery path: verify that the credentials and infrastructure required to retrieve it will still be available during an incident.
4. Restore into an isolated test environment
Never begin a routine test by overwriting the live site. Instead, create a temporary staging environment or isolated server, with its own database and storage. Restrict public access, block search indexing, and prevent the restored site from sending real customer emails, triggering payment captures, or writing to production integrations. Disable live webhooks and scheduled tasks until you have reviewed them. If the site uses a payment gateway, use its sandbox where supported. Test data may include personal information, so access, retention, and disposal rules still apply. For businesses without an internal technical team, a website maintenance and security plan should specify who is responsible for these safeguards.
5. Rehearse the recovery using a real backup
Choose a recent recovery point and follow the same documented procedure you would use after an outage. Record each step, the permissions needed, where the archive was found, and any manual intervention. Restore the database and files, configure the application, verify compatible runtime versions, and start the service in isolation. Do not quietly fix missing steps and then call the process proven: record each gap so the instructions can be improved. If your platform supports automated restore testing, use it as an additional control rather than a substitute for business-level checks. The key deliverable is a repeatable process another authorized maintainer could follow.
6. Test the website as a customer would
A successful server boot or HTTP 200 response is only the beginning. Browse representative pages on desktop and mobile. Open product images and downloadable files. Submit a test enquiry and confirm it reaches the intended test inbox. For stores, use sandbox payment methods and verify that an order is recorded correctly without charging a real customer. Check account sign-in, password-reset behavior in a controlled environment, admin access, and the most important integrations. Compare selected records against the source backup to catch missing or inconsistent data. Record screenshots or test results without exposing customer information. If a workflow cannot be safely exercised, document that limitation rather than marking it passed.
7. Validate data consistency and application behavior
Check that the restored database schema matches the deployed application version, especially after recent CMS, plugin, or software updates. Confirm expected row counts or sample records where appropriate, but remember that matching counts alone do not prove correctness. Look for broken media paths, missing permissions, incorrect environment variables, timezone issues, and background jobs that accidentally resumed. Review error logs and application health checks. A backup may restore technically while leaving a critical business process unusable. AWS also describes post-restore validation workflows, reinforcing the distinction between completing a restore job and verifying the recovered resource.
8. Measure recovery time and identify bottlenecks
Time the exercise from the moment a maintainer starts recovery until the agreed business-critical checks pass. Break down the elapsed time: obtaining access, locating the backup, provisioning infrastructure, transferring data, restoring, configuring, and testing. Compare the result with the RTO established earlier. If restoration takes longer than the business can tolerate, investigate the largest delays first. A very large media library, manual DNS changes, missing deployment documentation, or inaccessible credentials can dominate recovery time. Also compare the timestamp of restored data with the RPO. A backup that is easy to restore but too old may still be unsuitable for a transaction-heavy business.
9. Check domain, DNS, and external dependencies
Restoring the application is not the same as making the public website reachable. Document who controls the domain registration, nameservers, DNS records, hosting account, SSL certificate, and CDN configuration. Verify that authorized staff can access these systems during an outage. Do not change production DNS merely to prove that the staging copy works; use a test hostname instead. For a real migration or recovery, plan the DNS cutover and rollback carefully. If you are moving hosts as part of a recovery strategy, our published website hosting migration checklist covers a related but distinct set of launch and search-visibility risks.
10. Record ownership, escalation, and access
A restoration runbook should name the person who can authorize recovery, the maintainer who can execute it, and the fallback contact when that person is unavailable. Store the procedure somewhere accessible even if the main website and company email are down. Do not paste passwords or recovery keys into the runbook; reference a secure credential manager and an emergency access process. Specify who informs customers, who checks the recovered site, and who approves reopening live integrations. Clear ownership prevents an incident from turning into a series of unanswered messages between the hosting provider, developer, and business owner.
11. Schedule the next test and learn from failures
Repeat restore tests after material changes such as a platform upgrade, new payment integration, database migration, or hosting move, and at an interval that matches the website's risk. A quarterly exercise may be a starting point for some small sites, but it is not a universal compliance rule; high-change or high-impact systems may need more frequent testing. Keep a simple record with the backup date, test date, environment, result, elapsed time, issues found, and owner assigned to each fix. Retest failed steps. The purpose is not to produce a perfect report but to improve the probability that a real recovery will work when needed.
A practical website restore-test checklist
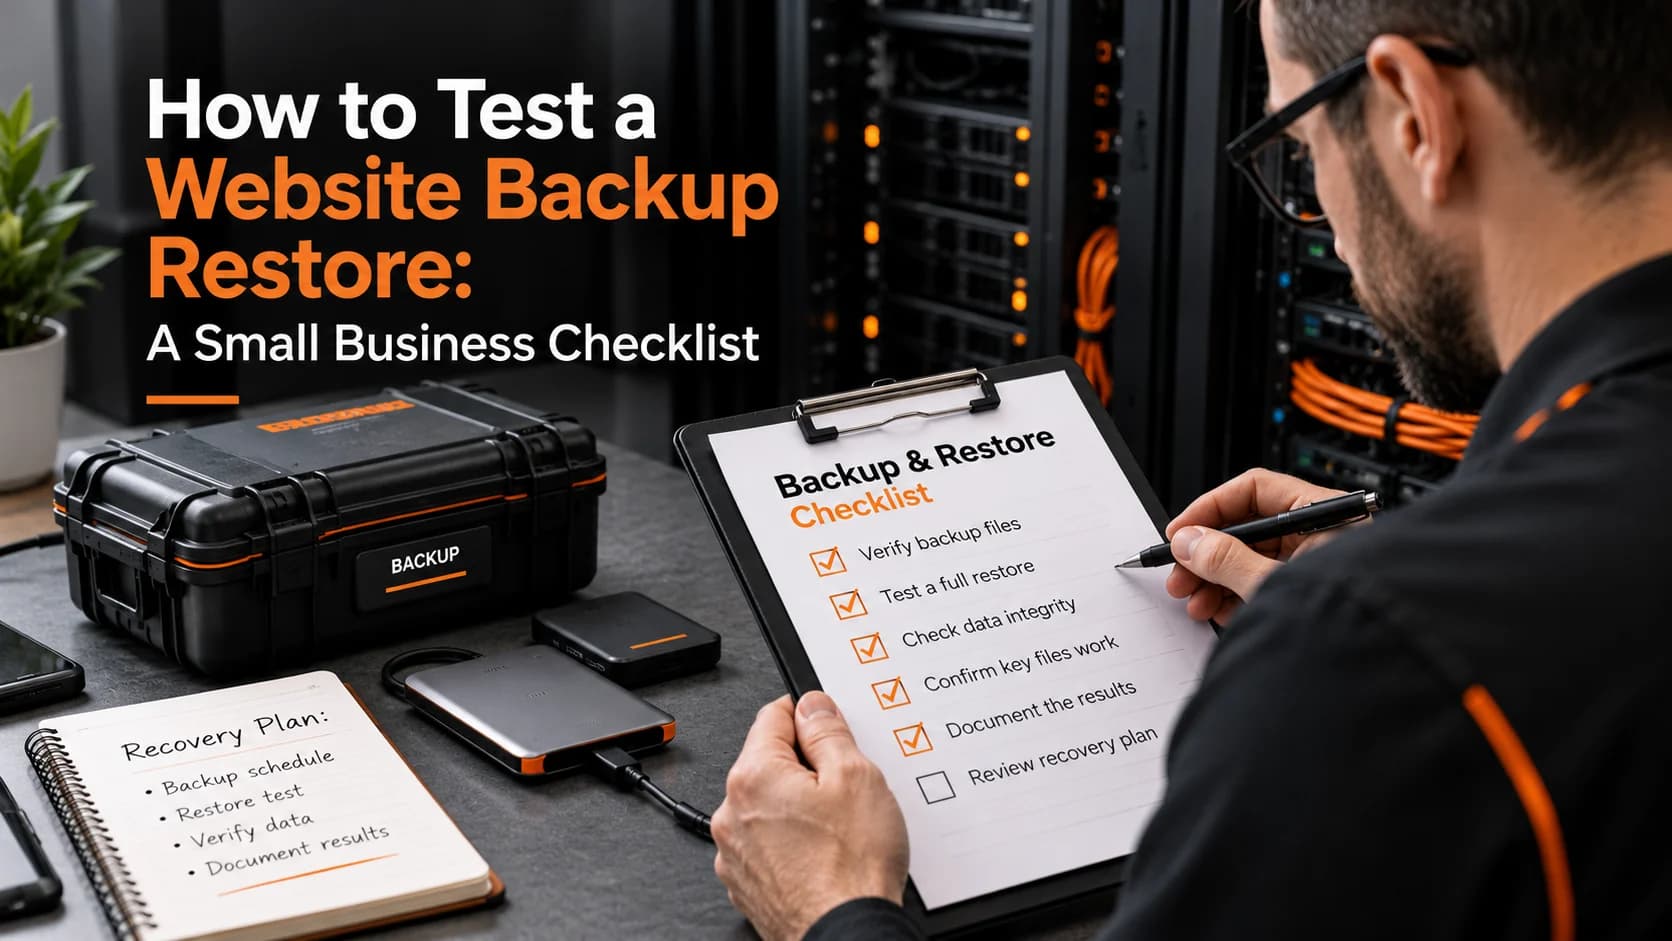
Before calling a restore test complete, confirm the following: the correct recovery point was identified; files, database, and media were restored; the test environment was isolated; public indexing and real notifications were disabled; representative customer journeys worked; critical records were checked; logs were reviewed; elapsed recovery time and data age met business targets; external dependencies and access were documented; and any failed checks have owners and follow-up dates. Keep the checklist short enough to use during a real incident. A business owner should be able to read the outcome and understand both what was proven and what remains uncertain.
When to get professional help
A site with a custom database, complex checkout, multiple integrations, or strict availability requirements deserves a recovery plan tailored to its architecture. The right support should help define recovery objectives, validate backups, rehearse restoration safely, and document ongoing responsibilities—not simply sell storage space. If your team needs assistance diagnosing an existing backup gap or planning a recovery exercise, explore DesDevSol's technical support services. Start by sharing your website platform, hosting setup, most important customer actions, and the last time a full restore was tested. That gives the discussion a practical starting point.